HappyHorse 1.0
HappyHorse 1.0 lets you generate cinematic 1080p clips with synchronized audio from a text prompt or image. Type your scene, hit generate, and walk away with broadcast-ready video and real sound in one pass.
How to Generate Video Using HappyHorse
Add Your Prompt
Type a prompt describing your scene, characters, camera movement, and mood. HappyHorse 1.0 understands natural language and follows instructions closely. The more specific your prompt, the more cinematic your output.
Choose Your Video Setting
Select your preferred aspect ratio, including portrait and landscape orientations. Set the video resolution of up to 1080p. HappyHorse 1.0 supports video duration of up to 20 seconds.
Generate & Download
Click generate and HappyHorse 1.0 will render incredibly cinematic videos, with native audio generation, smooth motion, and visual consistency. You can even edit it directly in ImagineArt AI video editor, if needed.
Generate AI Video with Sound in One Pass
HappyHorse 1.0 has a unified Transformer architecture that generates video frames and audio together in a single pass, producing synchronized dialogue, ambient sound, and Foley effects without a separate pipeline. What comes out is a finished clip with sound already baked in, ready to publish. For creators who need to move fast, that alone makes it worth using.
Multilingual Video with Native Lip-Sync
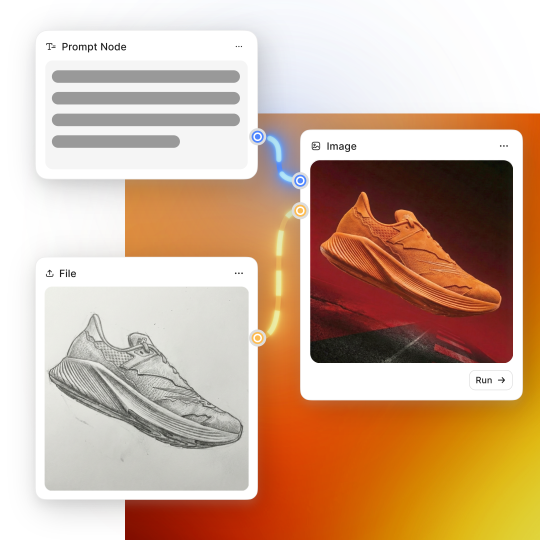
Multi-Modal Video Creation
Multi-Shot Storytelling
Choose a plan that fits your needs
Upgrade to get access to pro features and generate more and better
Kling
ByteDance
Minimax
Nano Banana
Gemini
Claude
Qwen
GPT Image
Runway
Grok
Trusted by Professionals and Creators from top Brands and Companies
FAQs
HappyHorse 1.0 is an AI video generation model available on the ImagineArt platform that turns text descriptions and images into cinematic video clips with synchronized audio. It uses a unified Transformer architecture to generate both video and sound in one pass, with no separate audio pipeline needed.
You describe your scene - subject, action, camera direction, mood, and audio intent - and HappyHorse 1.0 generates a clip that matches it. The model reads your prompt as instructions for both the visuals and the soundtrack at the same time. The more specific your description, the closer the output will be to what you had in mind.
HappyHorse 1.0 is coming soon to ImagineArt. It will be accessible through the ImagineArt platform and via the ImagineArt API, so both creators using the platform directly and developers building on top of it will be able to use it as soon as it launches.
Yes. HappyHorse 1.0 will be available via the ImagineArt API once it launches. Developers will be able to integrate HappyHorse 1.0 video generation directly into their own products and workflows using ImagineArt's API infrastructure.
HappyHorse 1.0 generates video and audio together in a single pass - dialogue, ambient sound, and Foley effects are produced simultaneously with the visuals. You do not need to add audio separately or use a different tool to sync it. The output comes with sound already baked in.
HappyHorse 1.0 natively supports seven languages for lip-sync: English, Mandarin, Cantonese, Japanese, Korean, German, and French. Lip movements are generated to match the spoken audio accurately. You select the language before generating and the model handles the rest.
HappyHorse 1.0 outputs video at native 1080p resolution. That is broadcast-ready quality with accurate lighting, rich color grading, and fine detail - no post-processing needed to get a usable result.
HappyHorse 1.0 supports six aspect ratios: 16:9 for landscape and YouTube, 9:16 for vertical TikTok and Reels, 4:3, 3:4, 21:9 for widescreen cinematic, and 1:1 for square social feeds. You choose the ratio before generating based on where you plan to publish the video.
Generation speed depends on the resolution you choose and the hardware processing your job. At 1080p on high-end GPU hardware, generation takes roughly 38 seconds. Lower-resolution previews complete in around 2 seconds, which is useful for testing prompts before committing to a full-quality render. On ImagineArt, generation time may vary based on server load.
HappyHorse 1.0 will generate a video from a vague prompt but the output will be less predictable. The model is built for strong prompt adherence, meaning it responds well to specific instructions about motion, framing, subject, mood, and audio intent. More detail in your prompt consistently leads to a result that matches what you had in mind.